Gang Liao
I build the systems that make ML work at scale — from silicon to software. At Meta , my work spans AI accelerator pre-silicon validation (ASIC), ads model-hardware co-design, GPU kernel & compiler optimization, model training & serving, data infrastructure, and agentic AI systems.
Trained by Daniel Abadi to never trust a single point of failure (Ph.D., University of Maryland).
Agentic kernel coding (KernelEvolve
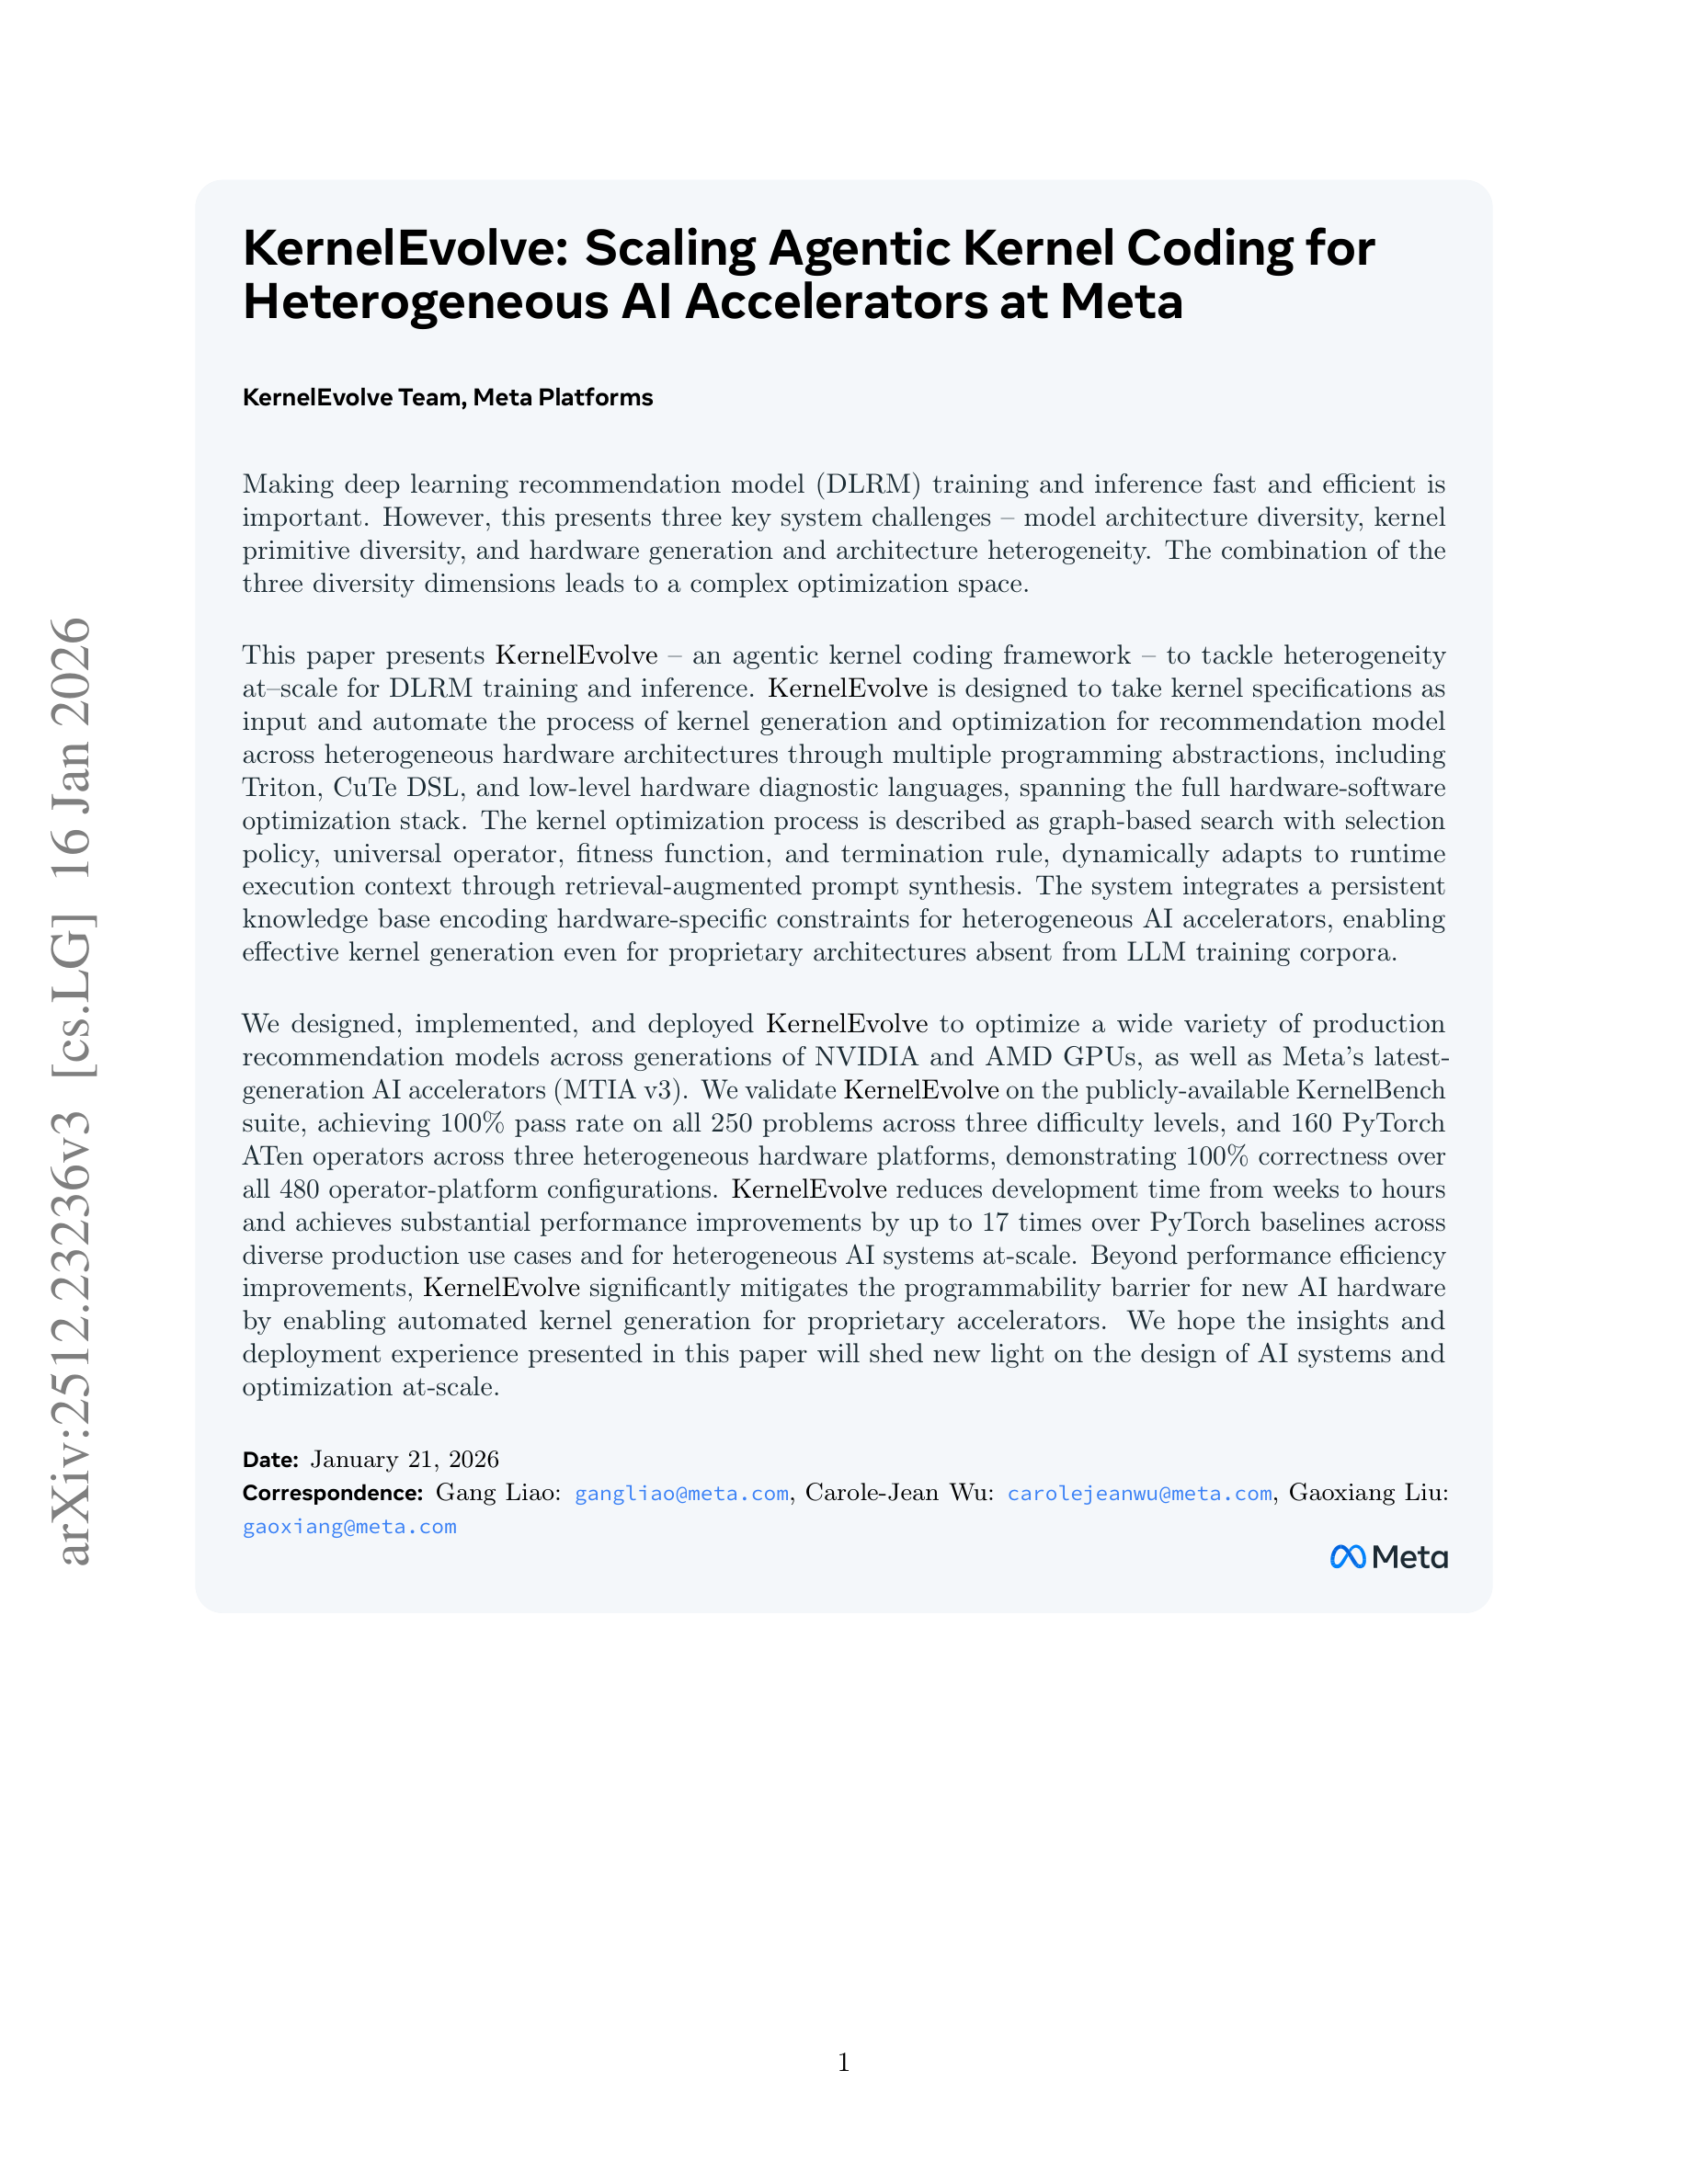 , Meta Blog, Import AI, ISCA'26) · distributed serving · across NVIDIA · AMD · MTIA
@ Meta
Post-training optimization · agentic RL infrastructure · data curation & synthesis · evals · experience graphs (Trellis, CIDR'27
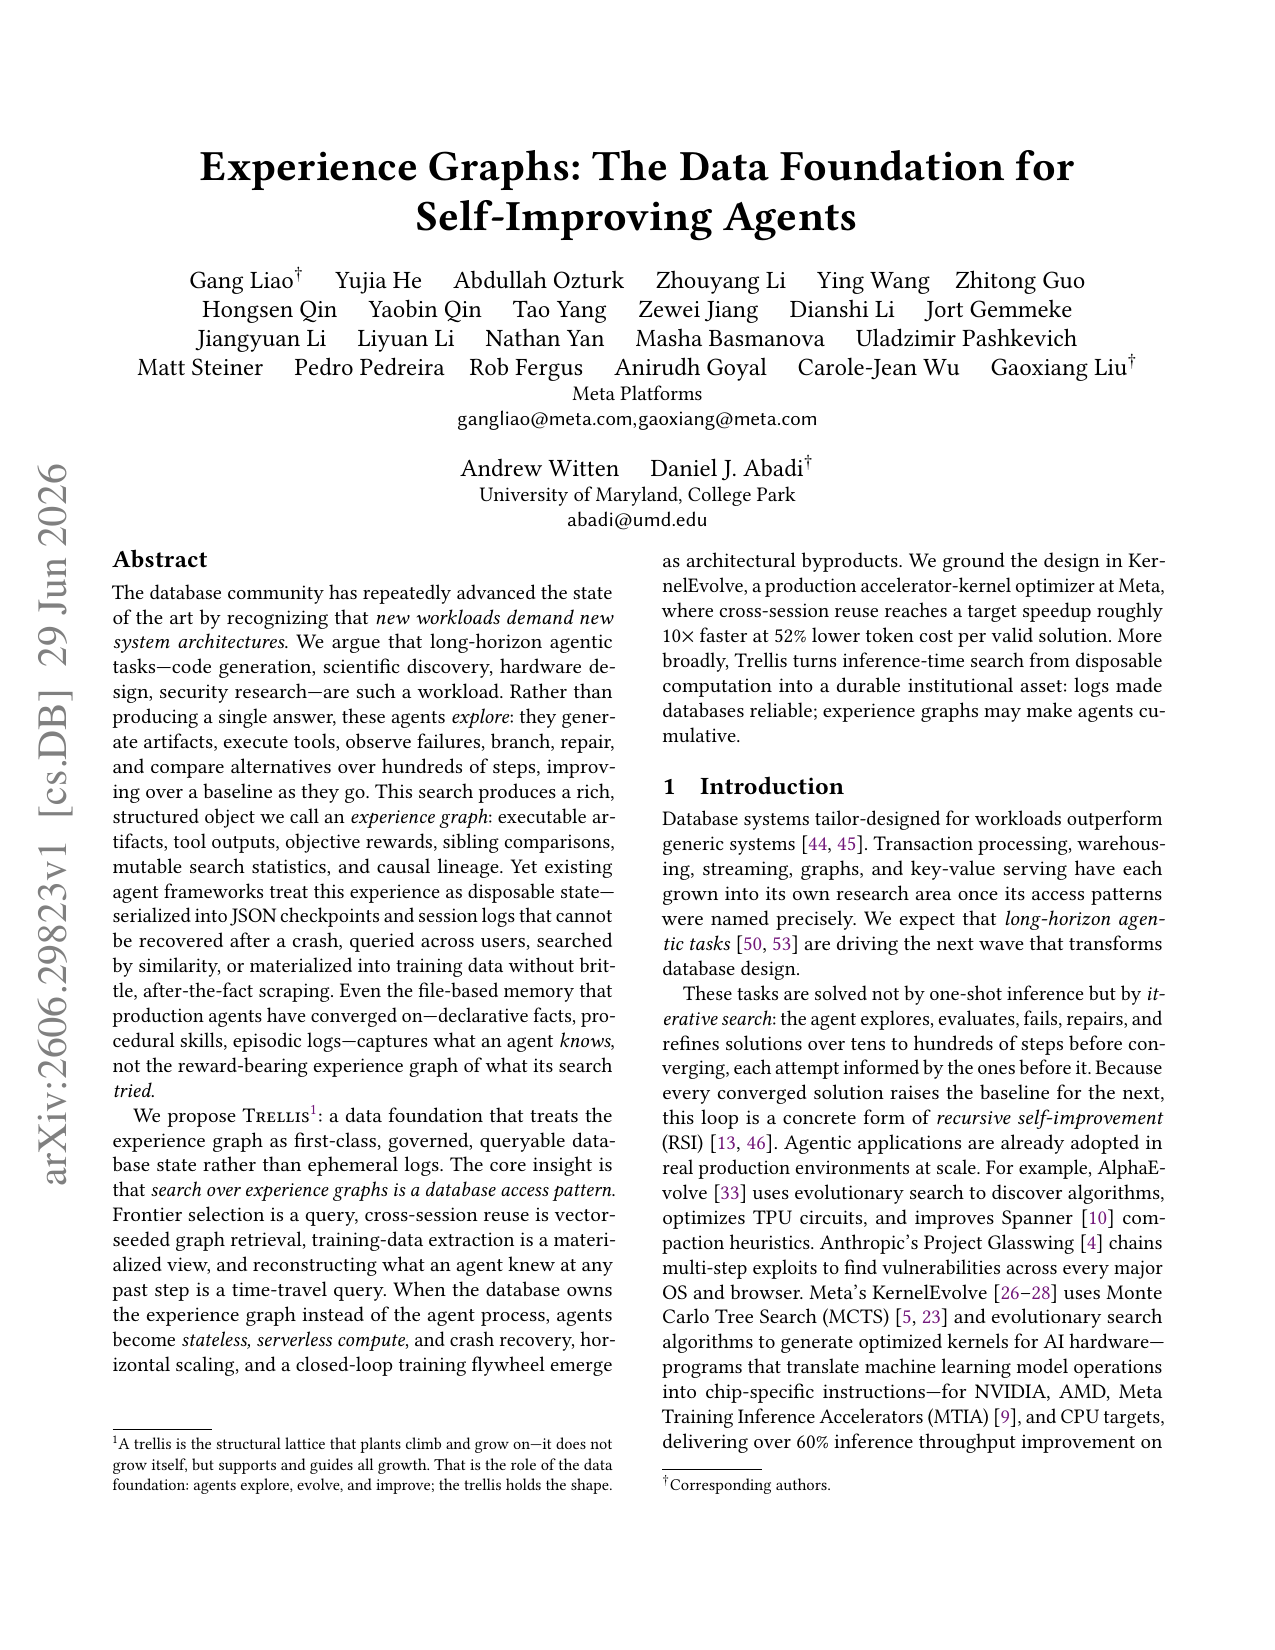 )
@ Meta
KV stores · ML column stores (Bullion, CIDR'25
 ) · file systems (FileScale, SoCC'23
 ) · schema evolution (BullFrog, SIGMOD'21
 ) · HTAP · vector databases
@ Meta · ByteDance · Microsoft Research
Core contributor to PaddlePaddle (22k+ ⭐) distributed parallel deep learning training (LLM) framework
@ Baidu Research
Latest writing
-
Muse Spark Open and Muse Glimmer, Layer by Layer: One Skeleton, a 30B Dense Model and an 816B Latent MoE
How Muse Spark Open (816B, 42B active) and Muse Glimmer 30B share one transformer skeleton, and the four things Spark Open changes on top of it.
-
CAKE from Scratch: Agents Write GPU Kernels, and the Compiler Learns from Their Mistakes
A beginner's guide to CAKE: AI agents write a checkable GPU schedule language, and the compiler turns their repeated failures into new checks.
-
DeepSeek-V4 and V4-Flash, Layer by Layer: Compressing Attention to Reach a Million Tokens
How DeepSeek-V4-Pro and V4-Flash compress the KV cache with CSA and HCA: at 1M tokens, V4-Pro needs 27% of V3.2's per-token FLOPs and 10% of its KV cache.